What Is an AI Model? A Beginner’s Guide to AI Basics
A spam filter, a photo tag, or a chatbot can all rely on a model that learned patterns from data. You meet these tools while sorting email, sharing pictures, or asking a phone for help. They can save time, but their results still need to fit your needs.
An AI model uses patterns learned from information to make predictions or decisions about new inputs. It is a tool, not a thinking person. An algorithm is a step-by-step procedure for processing data; training applies it to examples to produce a model. That distinction helps you understand what the software can do and why its answers may vary.
Key Takeaways
- A model uses learned patterns to make predictions or decisions.
- An algorithm gives steps; training those steps on examples produces a model.
- Models are tools, not people who think or understand.
- The useful question is not whether a model is intelligent, but what task it has learned to perform.
What Is an AI Model?
A spam filter is a simple example: it uses learned patterns to predict whether a new message belongs in the spam folder. The algorithm provides the procedure, while a model is the result after that procedure is applied to data. Some artificial intelligence uses explicit if-then rules, so not all AI uses machine learning.
A filter learns from messages marked as spam or acceptable, then makes predictions about new email. The result is an output based on the words, links, and other input features it learned to use. A system can follow rules instead, such as moving mail from a blocked sender.
A model’s prediction is an output based on learned patterns, not proof that the system understands the input as a person would.
A large language model, or LLM, is typically a neural network trained on large amounts of text. It can generate, summarize, translate, and analyze language. GPT means generative pre-trained transformer; GPT models are trained to predict the next word.
ChatGPT is a consumer-facing chatbot released in late 2022. An LLM is a text-trained model, while ChatGPT gives people a way to interact with language models. Stanford HAI’s AI glossary defines common terms such as models, algorithms, and training data.
How does an AI model learn from data?
During training, a model makes predictions on examples, compares them with feedback, and adjusts its parameters. These internal values change as the model tries to reduce errors. Good examples matter, since the model learns from the patterns in its training data.
Training teaches a model from examples; separate data checks how well it handles unfamiliar cases. In supervised learning, each example includes a correct answer, such as a picture labeled “cat” or “dog.” A model compares its prediction with that label and adjusts its settings.
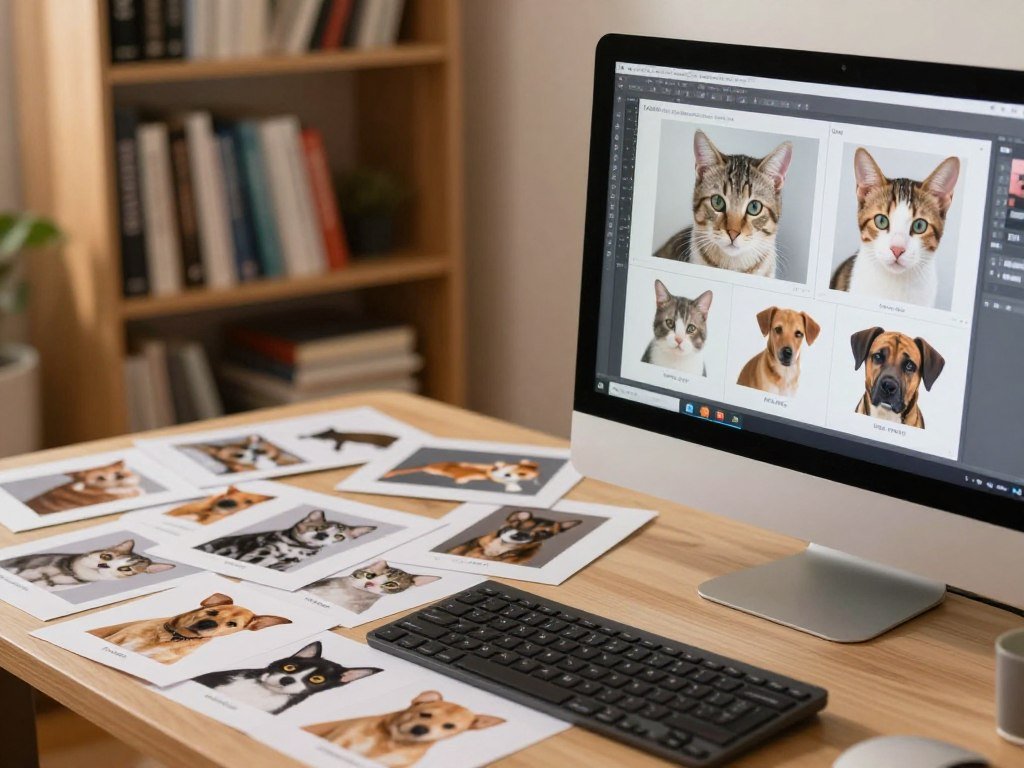
What happens during training
Imagine a dataset of cat and dog photos, each labeled with the right animal. At first, the model may confuse a small dog with a cat. It makes predictions, checks them against the labels, and adjusts its parameters across repeated examples.
That repeated process is machine learning. The model does not learn from a human-style explanation; it changes its internal settings to reduce errors on examples. The quality and range of the dataset affect what patterns it can learn.
How testing differs from training
Training examples teach the model. Validation examples come from separate data and help you tune choices, while test examples provide a final check. Cross-validation holds aside or resamples parts of the training data to evaluate performance.
After validation, deployment means using the model to make predictions on real inputs. A model does not improve just because it is in use; monitoring and, when useful, further training are needed to change it.
Use this basic sequence for a learning project:
- Prepare data, including clear examples and labels.
- Select an algorithm or model type for the task.
- Train the model on examples.
- Validate it on separate data.
- Deploy and monitor its predictions.
Keep test examples separate from training examples so the final check measures performance on data the model has not already learned from.
What types of AI models and learning methods are there?
The right model type depends on whether a task needs categories, numerical predictions, generated content, or an approximation of a costly simulation. The task sets the fit, not a model’s label. Supervised, unsupervised, and reinforcement learning use different signals to guide learning.
Each method fits a different kind of example or feedback. This table shows the basic differences, with a common task for each approach.
How learning signals shape a model
| Method | Training data | Learning signal | Example task |
|---|---|---|---|
| Supervised | Labeled examples | Correct output | Image classification |
| Unsupervised | Unlabeled examples | Patterns or clusters | Customer grouping |
| Reinforcement | Interaction with an environment | Rewards or penalties | Learning a game strategy |
Supervised learning uses known answers, while unsupervised learning looks for structure without labels. Reinforcement learning uses rewards or penalties from actions. Stanford HAI explains these terms in its AI definitions brief.
What deep learning adds
Deep learning is a subset of machine learning that uses neural networks with multiple layers. Each layer builds a representation from the output of earlier layers. For example, early layers may detect image edges, while later layers combine them into shapes.
During forward propagation, information passes through the network to produce an output. Backpropagation measures errors and sends adjustments back through the layers. These steps help refine predictions over many examples.
How generative, foundation, and surrogate models differ
Generative models create content, while discriminative models classify examples or predict values. Regression predicts continuous values, such as temperature; classification predicts discrete categories, such as a type of flower. Diffusion models, variational autoencoders, and transformers can generate content.
Large language models typically use the transformer neural-network architecture. Some transformers also process more than text. AI image generators often use diffusion models, which refine random noise into an image that matches a prompt.
A foundation model is pretrained on broad data, then adapted or fine-tuned for a task. Prompt-tuning guides its output with input cues, without changing the model in the same way as full training. Reasoning, multimodal, and agentic models are distinct developments; GPT, Claude, and Gemini include multimodal models.
An AI surrogate model is a cheaper-to-evaluate approximation of an expensive simulation or experiment. You select samples, build a model, then appraise its accuracy. Common methods include polynomial response surfaces, kriging, radial basis functions, support vector machines, and artificial neural networks.
Treat supervised, unsupervised, and reinforcement learning as different ways to learn, not as a ranking from weakest to strongest.
How can you train an AI model with your own data?
A first project works best when it has one clear task, a few well-defined classes, and examples you can label reliably. Start small, so you can spot confusing examples before they shape the model. Consistent, varied examples help a model recognize new cases.
To train an AI model with your own data, collect examples that reflect the cases you want it to handle. For a sound classifier, you might sort short recordings into “clap,” “speech,” and “background noise.” Give each class enough different examples to show normal variation.
Prepare a small dataset for a first project
Check that labels mean the same thing throughout the dataset. Make sure each class has examples, and set aside some examples for a final test. A lopsided or unclear collection can teach the wrong pattern.
Use this four-step plan:
- Choose one simple classification task.
- Gather representative examples for each class.
- Label and review the examples for mistakes.
- Train and test on separate examples.
Try browser-based image, audio, or pose classification
Google Teachable Machine is a browser-based option for image, audio, and pose classification. It uses transfer learning built on MobileNet, rather than training a neural network from scratch. Training often takes 5-30 seconds, based on sample count and browser hardware.
You can export a model to TensorFlow.js or TensorFlow Lite. Free online training is feasible for a small browser-based classification demo when a no-cost tool is available. Hosting or deploying the project may have separate costs.
A model trained in a browser can still make errors on new inputs. Try it with examples that differ from the ones used to train it, such as varied lighting or background sounds. Fix labels or add examples when the result does not fit the task.
For a 4-6-class Teachable Machine project, aim for 40-60 samples per class and check the results on examples kept out of training.
What tools and resources do AI models need?
A model’s training setup can be as small as a browser tool or as resource-intensive as cloud GPU computing. Choose for the workload, since the task affects the tools and compute you need. Costs depend on compute time, storage, data preparation, and whether you host the model after training.
Training tools include local frameworks, browser-based environments, and cloud services. PyTorch, TensorFlow, and Caffe2 are machine-learning frameworks. CPUs handle many general workloads, while GPUs support parallel processing for computationally intensive neural networks.
Lightning AI lists up to 30 free credits for its entry-level offering, plus 10 GB of free storage across its displayed offerings. Its free active CPU Studio has a four-hour session limit, and its entry-level offering allows one GPU per Studio.
One Lightning AI offering lists a $140 monthly seat price per user. These are details of that specific offering, not typical prices for all training tools. A small startup can also test an idea with existing services, as in these low-budget AI startup ideas.
Metrics help you judge model outputs. TP, TN, FP, and FN mean true positive, true negative, false positive, and false negative.
| Metric | Formula or definition | What it tells you | Limitation |
|---|---|---|---|
| Accuracy | (TP+TN)/(TP+TN+FP+FN) | Share of all predictions that are correct | Can mislead on imbalanced data |
| Precision | TP/(TP+FP) | Reliability of positive predictions | Misses false negatives |
| Recall | TP/(TP+FN) | Share of actual positives found | Can include false positives |
| F1 | Harmonic mean of precision and recall | Balance between the two | Hides the separate tradeoff |
The National Institute of Standards and Technology’s AI Metrology Center lists methods and tools for evaluating AI. Choose a metric that reflects the cost of the model’s mistakes, not just the score that looks highest.
Where do AI models show up in everyday life and business?
A speech recognizer turns spoken words into text, while a recommendation model predicts which item a user may want next. You already meet models in spam filters, photo tagging, navigation, and suggested music or products. In business, models can automate repetitive work and analyze large datasets.
Model capabilities vary by product and task. Some can work with long text, while others create speech, images, or music. The examples below show several current Gemini API capabilities.
- Gemini 4 Argon has a 1M-token context window.
- Gemini 3.5 Transcribe supports speech-to-text, speaker diarization, and word-level timestamps.
- Gemini 3.8 Flash TTS supports speech in 130 languages.
- Gemini Deep Research autonomously plans and executes multi-step research.
- Nano Banana 2.1 supports image generation and editing.
- Lyria 3.5 generates full-length songs.
Gemini 3.8 Flash is listed as stable. Gemini 3.5 Flash-Lite is a budget-friendly option for new API projects, and Gemini 3.8 Flash-Lite TTS supports 101 languages.
For marketing, models can help with writing, audience research, and routine campaign tasks. A useful AI marketing tool should fit a real workflow, with a person checking work before customers see it.
Earning money from AI models is not automatic. Income comes from paid model-development work or a useful product or service, not simply from training a model.
Start a business use case by naming the decision or routine task the model is meant to improve.
What can make an AI model unreliable?
A model can give a confident-looking answer and still be wrong when its data or evaluation does not match the real task. Five recurring failure patterns are biased data, inaccurate or unrepresentative training data, overfitting, underfitting, and data drift. Check outputs when errors could affect people or important decisions.
Overfitting means a model fits its training examples too closely, while underfitting means it misses useful patterns. Data drift happens when real inputs change from the data used during training. Biased or inaccurate data can also make language model output less reliable.
A benchmark score measures performance on a specific test, not every task a model might face.
As of October 27, 2026, Claude Opus 5.5 led BenchLM’s BenchAlign leaderboard with 86.66. That ranking used eight weighted categories and 60 benchmarks; the snapshot listed 86 models as Supported and 144 as Estimated.
BenchLM tracked more than 1,000 language models across 716 benchmarks in that snapshot. GPT-6 Astra had a 1.05M-token context window. Check a model on examples that reflect the people, inputs, and conditions it will actually encounter.
Conclusion
A useful first model is the smallest one that can solve a clearly defined task. A model is shaped by its data, so a suitable approach and careful checks matter more than a broad claim about artificial intelligence.
You can begin with a narrow business or personal task, then decide what a good prediction should look like. Keep a person involved when a wrong result could cause harm or waste time.
Before adopting one, write down the prediction you need and how a person will verify that it is good enough.
FAQ
What are the different types of AI tools?
AI tools include software for building models, preparing data, testing results, and accessing AI services. Model types describe what a model does, such as language, vision, or recommendations. For example, a writing assistant is a tool, while a language model may power its text features. Choose by task, then check whether the tool fits your workflow.
Is ChatGPT an AI language model?
ChatGPT is a chatbot, not the name of a language model itself. Released in late 2022, it gives people a way to interact with language models through conversation. Those models can generate or analyze text based on input. ChatGPT is the product people use, while a language model is the technology that can produce its replies.
What is an AI surrogate model?
An AI surrogate model approximates an expensive simulation or experiment and costs less to evaluate computationally. It learns a connection between inputs and results from selected samples. You can then use it to estimate results more quickly than running the full simulation each time. Its estimates still need checks against the original experiment or simulation.
What are the four types of AI models?
Four common categories are supervised learning, unsupervised learning, reinforcement learning, and deep learning. They are not mutually exclusive labels. Supervised, unsupervised, and reinforcement learning describe learning signals, while deep learning describes models built with multi-layer neural networks. A deep learning model, for example, can use supervised learning to classify labeled images.
Who is the most famous AI model?
ChatGPT is among the best-known AI products, but it is a chatbot rather than a model itself. It lets people interact with language models in a simple chat format. There is no objective ranking of fame, since recognition can differ by country, age group, and field. People may know the chatbot without knowing which model powers a feature.
How much do AI models cost?
A basic AI experiment can cost $0, while custom development and deployment can reach thousands of dollars or more. The price rises with the amount of data preparation, computing power, and staff time required. A free browser tool may suit a small demo. A product used by customers may add costs for hosting, support, and ongoing model work.
What is the most powerful AI model right now?
As of October 27, 2026, Claude Opus 5.5 led BenchLM’s BenchAlign leaderboard with a score of 86.66. That result measures performance on that leaderboard’s tests, not every possible task. A model that scores highest on one evaluation may not be the best fit for your needs. Compare models on the kind of input and output your task requires.
About The Author