What Is a Token in AI: A Beginner’s Guide to AI Models
An AI model does not take in a prompt as a person reads a sentence; it processes a sequence of smaller units. That difference matters when you ask a language model for help, then judge how much text fits in its reply. A tokenizer is software that breaks input into tokens and maps each token to an ID the model can process. The units affect how much text a model can handle at once. They can also affect what you pay when you use certain services. This guide focuses on language models, which work with text to answer questions, draft messages, and summarize documents. You will see why a sentence’s word count may not match its token count, and why a model’s settings matter. Knowing how those units work makes it easier to estimate what a model can handle and what its usage may cost.
Key Takeaways
- Tokens are pieces of text a model can process.
- A token may be a whole word or only part of one.
- Token counts depend on the model’s tokenizer.
- Input and output tokens can have different prices.
- The context window limits how many tokens fit in a request.
- A model’s tokenizer gives a closer count than a word estimate.
What Is a Token in AI?
The word “tokenization” can be split into smaller pieces instead of staying one unit. In generative AI, a token is a piece of text a model processes, such as a word, part of a word, or a group of characters and punctuation. It is not always a whole word. The tokenizer used by a model determines how the text divides.
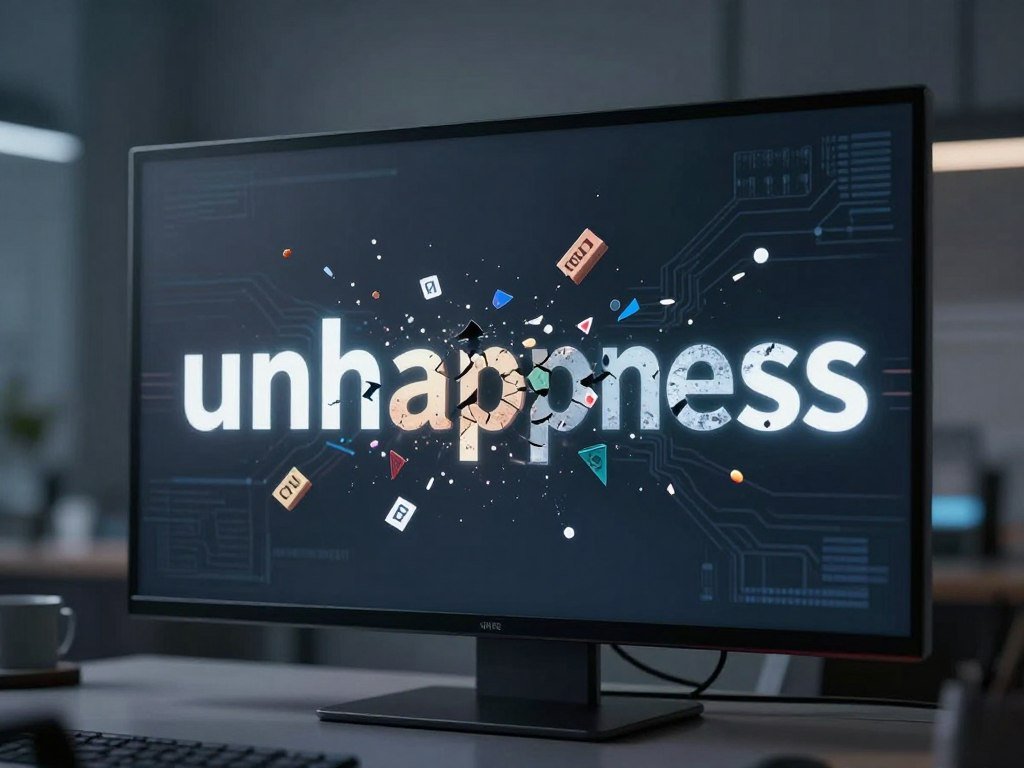
For example, a tokenizer might split the familiar word “unhappiness” into “un,” “happi,” and “ness.” Another tokenizer might choose different pieces. One written word can become several tokens, while a short group of characters may count as one. Punctuation can count as a separate piece, or it can join other characters.
A token is not a fixed synonym for a word; the tokenizer decides how a sentence divides.
That is why a word count cannot give an exact token count. A sentence with unusual names, punctuation, or spelling may divide differently from a sentence with common words. Token counts also differ across models because each may use a different tokenizer.
A rough English rule of thumb is that one token equals about four characters or 0.75 words. For a quick example, “The dog ran.” might use about four tokens, though the exact split depends on the tokenizer. This kind of example helps explain the idea, not predict a model’s exact count.
In short, what is a token in AI? It is one text unit that a generative model can process, not a guaranteed match for one word. A token in generative AI could be a full word, a word fragment, or punctuation. You can inspect how a model handles text with a tokenizer’s text-to-piece process. Treat the character and word estimates as a rough guide, not a guaranteed count for every sentence.
How Does Tokenization Turn Text Into IDs?
A tokenizer first decides which text pieces belong together, then represents each piece with an ID. That sequence of IDs is the form the model uses to process text. OpenAI GPT models use a subword approach called Byte-Pair Encoding, or BPE.
Each tokenizer assigns an ID to every piece in its vocabulary, the model’s set of token pieces. The ID is a number that marks a piece; it is not a meaning by itself. The model receives the text as a sequence of token IDs.
Word, character, and subword approaches
A word-based approach treats each word as one piece. This can work well for common words, but rare words and new names may not have their own entries. A character-based approach splits text into single characters. It can represent new words, yet a long sentence then needs many pieces.
Subword tokenization sits between those methods. It can keep a common word as one piece, while dividing a longer or less common word into smaller parts. For example, “garden” might stay whole, while a rare name might split into several pieces. The exact split depends on the model’s tokenizer.
How BPE builds common pieces
BPE starts with smaller text units and repeatedly merges frequent neighboring pieces. Over time, common combinations can become single tokens. Less common words may remain as shorter parts, which lets the vocabulary represent many words without storing every possible word as a whole.
For a simple example, a tokenizer could combine the letters in “play” into one piece, then keep “playing” as “play” plus “ing.” This is only an illustration; the tokenizer may split those words another way. BPE works from patterns in text, rather than a fixed list of whole words.
After the tokenizer chooses pieces, it maps each one to an ID. A made-up ID such as 418 can stand for one piece in an example, but real IDs depend on the vocabulary. Different models can produce different token counts for the same sentence because their tokenizers differ. Use the tokenizer for the specific model when an exact count matters, since the same text can split differently across models.
How Does a Model Use Tokens to Generate a Response?
After reading the input sequence, the model chooses one next token and adds it to the sequence. It uses the tokens already present to predict a likely next piece of text. Then the process repeats until the model reaches a stopping point.
The model’s vocabulary contains the pieces it can choose from. For each step, it predicts scores for possible next tokens, then selects one. The selected token becomes part of the sequence used for the next prediction. The model keeps building from the prompt and its own growing response.
This process creates readable output one piece at a time. The model is not simply retrieving a finished sentence from a list. Instead, each prediction depends on the sequence so far, including the prompt and any earlier response text.
For example, after “The coffee is,” a model might predict “hot.” It then uses “The coffee is hot” to predict what comes next. A different prompt may lead to a different choice, even when the first few words match.
Token prediction is a technical process, not proof that a model thinks like a person. The model uses patterns in language to select a sequence that fits its training and instructions. A system may stop when it reaches an end marker, a response limit, or another stopping condition set for the request.
The response length depends in part on how many pieces the model generates. A brief answer may use relatively few, while a detailed explanation needs more. A response is built piece by piece, so a longer generated answer requires more output tokens.
What Are Input and Output Tokens?
In a chat request, the words you send and the words the model generates belong to two different token counts. Input tokens are the material the model receives; output tokens are the response it creates. The split matters because services may count and price the two groups separately.
Input tokens include more than the prompt you type. A request can also carry instructions, earlier chat turns, text from attached files, and tool details. The following five parts commonly make up the input:
- Your prompt: “Summarize this report in three points.”
- System instructions: rules that set the model’s role or style.
- Conversation history: earlier questions and answers in the same chat.
- Attached documents: text from a report the model must review.
- Tool definitions: instructions for tools the model can call.
What counts as input
Input tokens are the pieces in all relevant material sent with the request. For example, a short new question can still have a large input count if the chat includes many earlier turns. A long attachment can add far more input than the prompt itself.
Not every service sends the same background material with each request. The instructions and tools included depend on how the app or API is set up. A usage report can help you see which parts count toward a particular request.
What counts as output
Output tokens are the pieces the model generates in its reply. A response with a short answer uses fewer output tokens than a long explanation. If the model creates other content, such as a tool call, the service may report that separately.
Many services set different rates for input and output, and output is often priced higher. That means two requests with similar total token counts can have different costs if one generates a much longer answer. Check whether a usage report separates input from output before comparing two requests.
How Does a Context Window Limit a Prompt?
A context window is the model’s working limit for the tokens it can process in one request. It can cover both the incoming material and the response the model creates. Both sides take space in limits that combine input and output.
A model’s context window is the maximum number of tokens it can process at once. In a simple 100-token context, a 9-token input leaves room for up to 91 output tokens. The real balance depends on the model’s rules and the request.
Some requests need only a small window. A short question with a brief answer uses less space than a request to review a long report and explain its main points. The right window size depends on the task, not just the length of your prompt.
Track these four parts as you plan a request:
- System instructions that shape the model’s behavior.
- Conversation history that remains part of the chat.
- Attached material the model needs to review.
- Response space for the answer you expect.
A large document can take up much of the available context before the model starts replying. Leaving too little space may cut off an answer or limit how much detail the model can provide. A larger window can help with long documents, but it does not guarantee a better answer.
For a comparison of context sizes in coding workflows, see these AI coding tools for developers. A product’s stated context window can also vary by plan. Leave room for the response instead of filling the entire available window with input.
How Much Do AI Tokens Cost?
At standard speed, GPT-6 Luna costs $0.10 per 1 million input tokens and $0.50 per 1 million output tokens. Rates change by model and token type, so a million input tokens does not have one set price across all models.
API prices are often listed per million tokens, with separate rates for input and output. At standard speed, GPT-6 Astra costs $10.00 per million input tokens and $50.00 per million output tokens. The table compares standard rates with cached input and Batch API rates.
Standard API rates
Standard prices in the table apply to regular-speed API use. Input and output rates differ for each model, so a request’s mix of prompt text and generated text affects its bill. A million tokens is a pricing unit, not a requirement to send that much text.
Cached input and Batch API rates
Cached input rates apply to input tokens that qualify as cached. Batch API rates apply only to use of the Batch API. They are separate from standard rates, so select the pricing column that matches how the request runs.
| Model | Standard input per 1 million | Standard output per 1 million | Cached input per 1 million | Batch input and output per 1 million |
|---|---|---|---|---|
| GPT-6 Astra | $10.00 | $50.00 | $1.00 | $5.00 input, $25.00 output |
| GPT-6.1 Sol | $2.00 | $10.00 | $0.10 | $1.00 input, $5.00 output |
| GPT-6.1 Terra | $1.00 | $5.00 | $0.05 | $0.50 input, $2.50 output |
| GPT-6 Luna | $0.10 | $0.50 | $0.01 | $0.05 input, $0.25 output |
Regional processing uplift
Eligible models released on or after March 5, 2026, have a 10% price uplift when used with regional-processing endpoints. The uplift applies to those eligible models and endpoints, not every model or request.
Some services also set token-per-minute, or TPM, limits. These limits control how many tokens a system can process over time. They affect throughput rather than directly setting the price per token.
To keep API costs in view while planning a project, consider advice on monitoring API token usage. Compare the model, token type, processing mode, and endpoint before estimating a bill.
How Can You Estimate Token Use Before Sending a Prompt?
A quick English estimate is that 100 tokens represent about 75 words, but the actual count follows the model’s tokenizer. Use the estimate for planning, not as an exact measure. A word count alone cannot account for every token split.
One prose page is about 500-700 tokens, while an hour of audio transcript is roughly 9,000-16,000 tokens. A 300-page book is roughly 150,000-200,000 tokens. These figures are rough because language, script, tokenizer, and writing style all affect the count.
| Reference material | Approximate token count | Qualification |
|---|---|---|
| 100 tokens | About 75 words or 400 characters | Rough English estimate |
| One prose page | About 500-700 tokens | Page length and style affect count |
| One hour of audio transcript | Roughly 9,000-16,000 tokens | Transcript content changes the count |
Text in other languages may use a different number of pieces for the same idea. Code, numbers, symbols, and unusual formatting can also change the count. The 0.75-word estimate is unreliable for code and text heavy in numbers or symbols.
Use these three steps to plan a request:
- Draft the complete input, including instructions and material you plan to attach.
- Count it with the tokenizer for the target model.
- Reserve context space for the response you expect the model to produce.
A model-specific tokenizer gives a more reliable count than a general estimate because it uses that model’s vocabulary. For repeated tasks, test a typical prompt, not only a very short sample. Measure representative prompts in the target model before using a rough estimate to budget real requests.
Does an AI Token Mean the Same Thing as a Crypto Token?
The word “token” has separate meanings in AI processing and financial markets. An AI token is a unit a model processes, while a financial-market token represents an asset digitally. Neither is automatically the same as a coin.
A financial-market token can represent an asset such as a stock, bond, fund, or house. A person may hold that digital representation in a wallet. This form of tokenization is distinct from cryptocurrencies such as Bitcoin, which are not simply digital representations of another asset.
Bitcoin is a cryptocurrency, not an AI processing unit. Financial-market tokenization refers to turning an asset’s representation into a digital form. The word “token” can describe both ideas, but their uses and roles differ.
AI tokenization also reaches beyond written text. Visual models can map pixels or voxels into discrete tokens. Audio models can tokenize spectrograms, which show sound patterns, or represent meaning drawn from sound.
For example, a picture model may process a visual input as pieces, while an audio model may process sound data. Text prompts and reference images can guide an AI image generator, though its visual tokens are not coins or assets.
Check the surrounding context: a model’s sequence points to AI tokens, while a digital wallet and asset point to financial tokenization.
The context around the word usually makes its meaning clear. A model, prompt, or sequence signals AI processing; a wallet and an asset signal financial tokenization.
Conclusion
For everyday use, remember that a token count is a model-specific measure of processed content, not a simple word count. The tokenizer and the full request affect how much fits and what usage costs. A small test can prevent surprises.
Run one representative prompt through the tokenizer for the model you plan to use. Compare its input count with the space needed for a response, then apply the rates for that model and request type. Check one real prompt with the intended model’s tokenizer before planning a larger workload.
FAQ
How much text is 100 tokens?
One hundred tokens represent about 75 English words or 400 characters as a rough estimate. The actual count depends on the tokenizer, language, and writing style. A sentence with common English words may fit that estimate, while code or text with many numbers and symbols can differ. Use the target model’s tokenizer for a more exact count.
What does "token" mean?
A token is a unit of text that a model processes. It may be a whole word, part of a word, or a combination of characters and punctuation. For example, a tokenizer might split “unhappiness” into smaller pieces rather than keep it as one unit. The tokenizer determines the pieces, so token counts do not always match word counts.
How does ChatGPT tokenize?
OpenAI GPT models use Byte-Pair Encoding, or BPE, for subword tokenization. BPE joins frequent neighboring pieces so common text sequences can become single tokens. The tokenizer then maps each piece to an ID, and the model processes the resulting sequence of IDs. Exact splits depend on the model’s tokenizer, so different models can count the same text differently.
How much do AI tokens typically cost?
AI token rates depend on the model and whether the tokens are input or output. At standard speed, GPT-6 Luna costs $0.10 per million input tokens and $0.50 per million output tokens. GPT-6 Astra costs $10.00 per million input tokens and $50.00 per million output tokens. Cached input, Batch API use, and eligible regional endpoints can have different rates.
Is bitcoin an example of tokenization?
Bitcoin is a cryptocurrency, while financial-market tokenization represents another asset digitally, such as a stock or bond. Neither meaning is the same as an AI processing token. AI tokens are units a model handles as it processes text, images, or audio. The surrounding words help show which meaning applies: a model points to AI, while a wallet and asset point to finance.
About The Author