What Is RAG in AI? A Beginner’s Guide to Retrieval
A polished AI response can sound certain even when it misses a recent policy change or a detail specific to your workplace. That can matter when a user needs accurate guidance, not just clear language. What is RAG in AI? It is an approach that lets an application consult relevant information while preparing an answer. An embedding is a numerical representation of text that helps a search system compare meaning. This guide explains how AI can use outside knowledge, what that can improve, and where the limits remain. You will also see how the information behind a response affects what the system can say. Understanding where an answer’s supporting information comes from is a useful first check before relying on it.
Key Takeaways
- RAG pairs information retrieval with language models that write responses.
- A knowledge base can hold files, database records, and other source material.
- The system retrieves selected context for each query, rather than sending every source.
- Good answers depend on useful, current, permitted information and relevant search results.
- RAG can help with changing knowledge, but it cannot guarantee accuracy.
What Is RAG in AI?
RAG stands for retrieval-augmented generation, a method that lets an AI application look up information before generating a response. In simple terms, the system searches useful material first, then gives it to a language model to help shape an answer. Retrieval means finding information; generation means writing new text from the available context.
In an LLM application, the model receives the user’s query along with relevant information found in an external collection called a knowledge base. RAG combines retrieval with generation; it does not replace the language model. The model uses the added material to form a response that better fits the question.
Retrieved context can help an answer use relevant information, but it cannot make a weak or missing source reliable.
A “RAG model” usually means the connected application or pipeline, not a new type of language model. The application includes the retrieval process and the language model that writes the response. It may also connect to company records, product information, or other sources that the model did not learn during training.
The setup can give an LLM access to information that changes over time, without training the model again for every update. Its usefulness still depends on whether the search finds the right material. A response may sound natural even when the retrieved information does not answer the user’s question.
The language model still writes the answer, but the retrieved material can give it more relevant context.
What are the main parts of a RAG system?
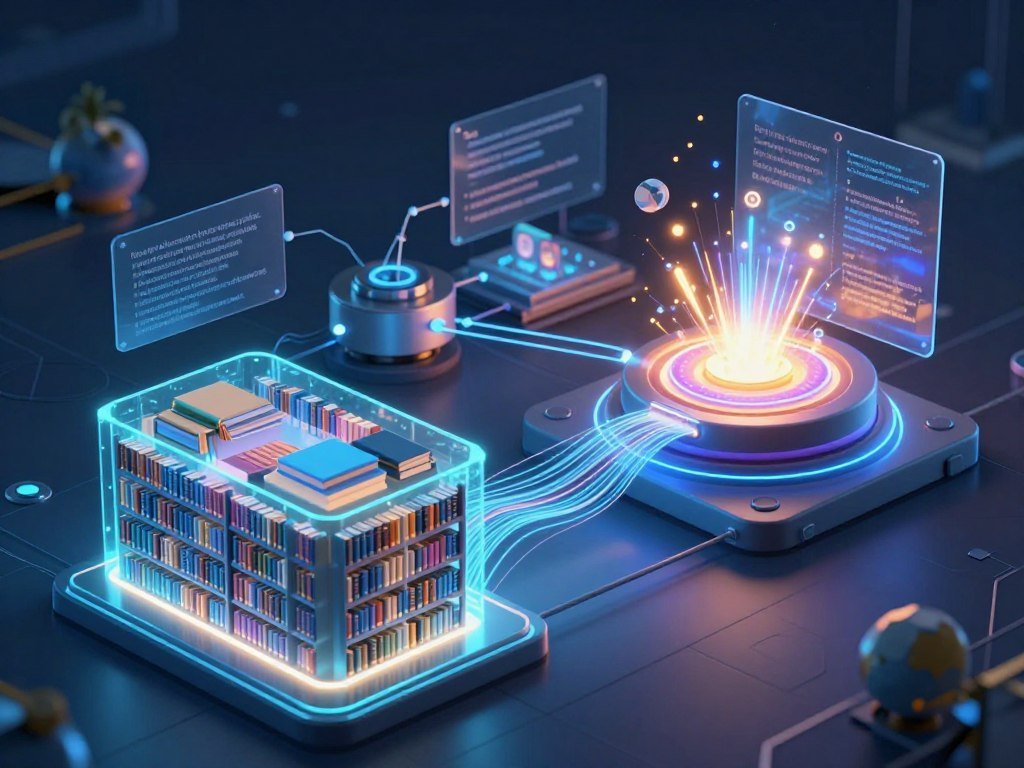
A basic RAG system has four parts: a knowledge base, a retriever, an integration layer, and a generator. Together, these systems find information, prepare it for the model, and produce a response. The LLM is one part of a RAG model, not the whole application.
The parts can work with files, database records, or long-form text. A knowledge base is not always a folder full of documents. Its contents depend on the task and the information the system is allowed to use.
What makes a RAG model work?
The knowledge base holds the source material the system can search. It might include company procedures, product records, or a collection of reports. The quality and scope of that information shape which answers the application can support.
The retriever looks for material that matches a query. It can search by meaning, exact words, or both. Its job is to select useful passages, not to write the final response.
How an LLM uses retrieved context
The integration layer connects the retrieval results to the generator. It combines the user’s question with selected information and sends both to the LLM. This handoff gives the model context to use as it writes.
The generator is often an LLM that creates a response in natural language. It may explain the retrieved information, combine details, or answer in a set format. The connected system is the RAG model; the generator alone does not perform the full retrieval task.
Why the knowledge base matters
Source material sets the limits of the system’s knowledge at answer time. A policy assistant with only policy documents cannot answer questions about a person’s private account record. A support assistant may need product guides and current service details to answer well.
Clear boundaries also matter. The system should retrieve only information that fits its purpose and that the user can access. The system works only when those parts pass useful source material to the model in a form it can use.
What happens inside a RAG pipeline?
Before a user asks anything, a RAG system prepares its source material so it can be searched in smaller, meaningful pieces. First, it indexes the source; later, it retrieves selected context for a query. The stored knowledge base is larger than the context chosen for one response.
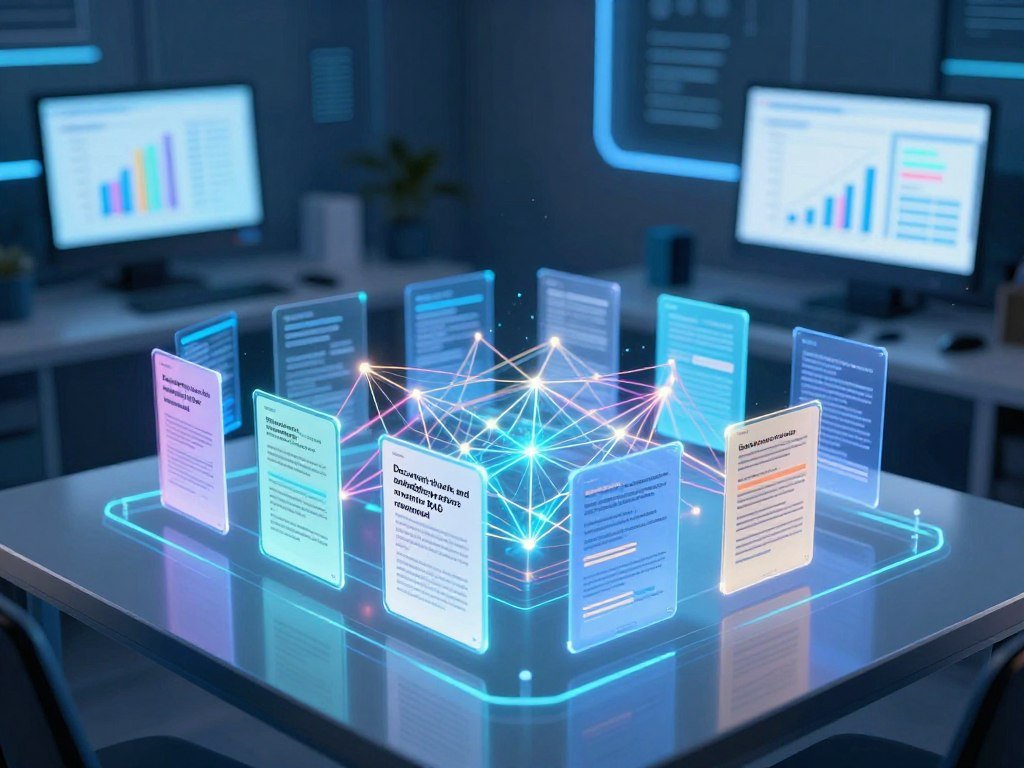
A chunk is a passage made by splitting a document or other source into smaller pieces. The system creates an embedding vector for each chunk and stores the text and its vector in a vector database. An embedding vector is a set of numbers that represents meaning for search.
Preparing and indexing source material
During indexing, the system turns source data into searchable chunks. It stores the chunks with their embeddings, often in a vector database. The original material remains the source; the stored vectors help the search process compare meaning.
| Stage | Input | What happens | Output |
|---|---|---|---|
| Document preparation | Source documents | Split into chunks | Searchable passages |
| Embedding and storage | Chunks | Create and store vectors | Indexed knowledge base |
| Query retrieval | User question | Compare query embedding with stored embeddings | Ranked chunks |
| Generation | Query and ranked chunks | Provide context to LLM | Generated response |
Retrieving context for a user’s question
At query time, the system creates an embedding for the question and compares it with stored document embeddings. It ranks likely matches, then sends selected chunks with the question to the LLM. Those passages become context for that answer, not a replacement for the full knowledge base.
Source data and its embedding representations need updates when the original material changes. Those updates can run through real-time processes or periodic batch processing. A newly changed source is useful only after the system’s searchable representation is refreshed.
A typical indexing and retrieval pipeline follows this pattern, from chunk creation through the context sent to the model.
What does RAG look like in a real example?
If an employee asks how much annual leave is available, a useful answer may depend on both the leave policy and that employee’s past leave record. Both sources matter: one sets the rule, while the other shows personal use. The system needs the right source for each part of the question.
An HR assistant could retrieve the annual-leave policy and the employee’s own leave record. The policy might explain the allowance and how leave accrues. The record could show how much leave the employee has already used or has left.
The LLM receives the question and the retrieved details, then combines them into a natural-language response. It might explain the remaining leave and point to the relevant policy rule. It should not guess at personal details that the search did not find.
A RAG answer can only be as specific as the permitted source material it retrieves. A general policy can explain a rule, but it cannot confirm one person’s account balance. Other common uses include:
- A support assistant retrieving product documentation.
- An internal assistant retrieving company procedures.
- A research assistant retrieving relevant reports.
Each example relies on different source material, and access rules can limit what a system retrieves. A help desk may search public product guides, while an employee tool may need restricted records. For a personal answer, the system needs authorized access to the relevant user-specific record, not just the general policy.
What can RAG improve, and what can still go wrong?
RAG can reduce unsupported answers, but a weak search result can still steer the model toward a wrong or irrelevant response. Grounded does not automatically mean correct. Irrelevant retrieved information can produce an answer that sounds supported but misses the question.
Poor chunking can split key details apart, while weak embedding choices can make useful passages harder to find. The model may then answer from incomplete or off-topic context. Search quality is part of answer quality, but retrieval alone does not prove a response is accurate.
Better matching does not guarantee a correct answer
Even a close match can lack a key fact or contain old information. Check whether the retrieved passage supports the answer’s actual claim. A citation or a relevant-looking passage does not establish that every statement follows from it.
For more on checking generated claims against their source text, see these AI research tools and source checks. A system can retrieve a passage and still misread it or use it beyond its meaning.
Search methods can improve relevance
Hybrid search combines semantic search with keyword search. Semantic search looks for meaning, while keyword matching can find exact terms such as a product code or policy name. A reranker can score the results and move more relevant items higher in the list.
These methods can improve relevance, but they cannot guarantee accuracy. Retrieval can also use embeddings for images, audio, and video, alongside text embeddings. That lets a system search different kinds of data, provided it can process those formats.
Protecting and retrieving different kinds of data
Data protection matters when a knowledge base contains private or business records. An unencrypted vector database may expose original data if someone breaches it. Access rules should match the user and the task, not merely the search query.
- Test retrieval against questions that represent real user needs.
- Inspect whether returned passages actually answer those questions.
- Review access controls and encryption for sensitive data.
Do not enter passwords, payment-card details, or confidential company information into an unapproved service without clear data controls. A retrieved passage should be checked for relevance and permission before it is treated as dependable context.
When should you use RAG instead of long context or fine-tuning?
Use RAG when the answer depends on information that changes or lives in a large external knowledge base. For changing data, retrieval can select current material instead of sending a whole collection with every query. Long-context LLMs fit large supplied inputs, while fine-tuning changes model behavior.
A long-context model can process material supplied within one context window. RAG searches outside the model and supplies selected information. RAG can reduce the amount of text sent per query, but it still needs retrieval and data maintenance.
Choose retrieval for changing external knowledge
RAG suits large or changing external collections, such as updated manuals, policies, or records. The system can search the knowledge base at answer time and send selected passages to the model. That can use fewer tokens per query than supplying a large collection at once.
Retrieval still takes work. Source data must stay current, and the search must find useful context. If the task centers on one long file that fits in a context window, searching a separate knowledge base may add needless steps.
Choose long context or fine-tuning for different jobs
Long-context LLMs work well when you need to summarize or reason over a large input that fits within one context window. Fine-tuning means giving a model additional training on domain-specific examples. It can change the model’s behavior, but it does not fetch current facts from an external source.
RAG changes the information available at answer time; fine-tuning changes how the model responds. Some applications combine both, such as a model trained for a steady output style that retrieves changing company rules.
| Approach | Where task information comes from | Best fit |
|---|---|---|
| RAG | Selected external sources | Changing knowledge base |
| Long-context LLM | Material supplied in one context window | Large input to summarize or reason over |
| Fine-tuning | Examples used for additional model training | Stable domain behavior or output style |
Choose the method by asking whether the main need is current information, analysis of a supplied input, or a more specialized model behavior.
How is RAG different from agentic AI and GraphRAG?
A standard RAG request follows a defined route, while an agentic system can choose and revise actions across multiple steps. That difference affects how much freedom the system has. Use a bounded RAG path for a direct search-and-answer task; use agents when a task needs planning or tool use.
Agentic AI is a multi-step system that plans, uses tools, observes results, and can adjust its next move. An agent might search more than once or change its approach after an initial result. That flexibility can help with unclear tasks, but it also adds steps that need control.
A bounded retrieval path versus a multi-step agent
Agentic search can improve dense RAG and narrow its gap with GraphRAG. GraphRAG retains an advantage for complex, multi-hop reasoning, where an answer depends on several connected facts. A RAGSearch benchmark comparison tests dense RAG and GraphRAG under standardized model and retrieval conditions.
One workflow can combine these approaches. Deterministic rules can control approvals and routing, agents can handle ambiguous cases, and human reviewers can assess high-risk or low-confidence decisions. For a broader look at AI coding agents and review, see how they can inspect files and propose changes that still need approval.
Fixed, event-triggered workflows differ from agents that take several steps toward a goal. A business workflow may use both, with rules for routine actions and an agent for harder questions. Learn more about AI software and business workflows when weighing those patterns.
Following relationships across documents
GraphRAG is a graph-based retrieval approach. It builds a structured knowledge graph from extracted nodes and edges: nodes represent things, while edges represent relationships between them. Search can follow those links rather than relying only on text similarity.
Retrieval can also follow references through text and metadata without building a full graph. For example, a chunk might point to “Section 4.2.1.” The system can search a metadata index for that section alias, then retrieve the linked passage.
Graph links can help trace connected information, while metadata references can connect chunks with known labels. Keep human review in the workflow when an answer could trigger a high-risk decision.
Verdantix’s GraphRAG analysis explains how nodes and relationships can support retrieval across connected concepts.
Which tools can help you build a RAG application?
A beginner can build a RAG application with a modular framework, a visual workflow platform, a document-focused engine, or a managed search service. Each type offers different controls and document support. Choose by the source formats and features your project needs, not by a tool’s label.
Some tools connect existing models and data systems; others manage more of the search or document workflow. Their capabilities differ, so they are starting points rather than interchangeable products.
Frameworks for connecting retrieval and generation
LangChain offers integrations for models, embeddings, vector stores, data sources, retrieval strategies, and evaluation tools. It suits projects that need modular connections. Dify provides a visual workflow editor and supports document ingestion and retrieval for PDFs and PPTs.
RAGFlow focuses on extracting text, tables, and structure from complex documents such as PDFs. It also supports GraphRAG. These tools address different needs, especially when document layout or workflow design matters.
| Tool | What it helps connect or process | Notable capability |
|---|---|---|
| LangChain | Models, embeddings, vector stores, sources | Retrieval strategies and evaluation |
| Dify | LLM application workflow and documents | Visual editor, PDF and PPT ingestion |
| RAGFlow | Complex documents | Text, table, and structure extraction plus GraphRAG |
Managed search and from-scratch examples
Google Cloud Agent Search is a managed search and RAG builder. Google Cloud Vector Search supports semantic and hybrid search over embedding collections. These managed services can reduce setup work, while the exact fit depends on the application’s data and controls.
A from-scratch example can pair Ollama with BGE-base-en-v1.5 embeddings and Llama-3.2-1B-Instruct. It ranks chunks with cosine similarity, a measure of how closely two vectors point in the same direction, and retrieves the top 3 by default.
That example gives you control over each part, but also leaves more setup and testing to you. LangChain, Dify, RAGFlow, and managed search services solve different parts of the build. Pick tools by matching their documented capabilities to your source formats and the control your project requires.
Business AI software options can help you compare assistants and workflow platforms beyond RAG-specific tools.
How do you build a basic RAG system?
Start with one task where a better answer depends on a clearly defined set of trusted information. A narrow task makes it easier to see whether retrieval helps. Use source material that is both authoritative and permitted for your application.
Then connect source ingestion, chunking, embeddings, retrieval, and answer generation. The system indexes chunks and their embeddings before it searches for ranked passages to give the LLM. Begin with a small set of material that matches the task.
Start with a focused use case and trusted sources
Choose a recurring question with a clear answer in approved source material. Gather the documents or records that support it, then check their accuracy and access rules. A broad goal such as “answer anything about the company” makes a first test hard to judge.
If you are testing a small AI business idea, low-budget AI startup ideas can help you think about a narrow first use case.
Connect ingestion, retrieval, and answer generation
Index the source material as chunks and create an embedding for each one. At query time, compare the question’s embedding with stored vectors, rank likely matches, and pass selected passages with the question to the LLM.
Test the result with realistic questions. Inspect both the retrieved passages and the written answer, since a fluent response can hide a poor match. Refresh source data and embeddings when information changes, either in real time or through periodic batches.
- Choose one use case.
- Gather and check source material.
- Index chunks and embeddings.
- Test realistic questions and inspect retrieved passages.
- Set a refresh schedule for source data and embeddings.
Keep the first test small enough that you can inspect both the retrieved passages and the answer they produced.
Conclusion
RAG is most useful when a language model needs access to specific information that may change or sit outside its training data. Useful answers still depend on source quality and retrieval relevance. A weak match can leave the model with little support, even when the final response reads smoothly.
Pick one recurring question and check whether the system retrieves passages that genuinely answer it. Look at the evidence before judging the response, then decide whether the task needs a small pilot. Choose one real question, test the retrieved evidence, and use that result to decide whether a small RAG pilot is worthwhile.
FAQ
What is RAG in AI and how does it work?
RAG means retrieval-augmented generation, a method that gives a language model information from an outside collection. First, the system indexes source material as chunks and embeddings. When a user asks a question, it retrieves relevant chunks and sends them with the query to an LLM. The LLM then uses that context to generate a response.
What is the full meaning of RAG?
RAG means retrieval-augmented generation. “Retrieval” refers to finding information from a connected source, while “generation” refers to the model’s written answer. The retrieved material gives the LLM context for a response. RAG describes the combined retrieval-and-generation approach, not a separate kind of language model.
Can you provide a diagram of the RAG architecture?
Yes. A compact text diagram is: documents or databases -> chunks and embeddings -> vector database -> query retrieval -> LLM with context -> response. The source collection is prepared before a question arrives. At question time, the system selects passages and sends them with the query to the model.
Is ChatGPT RAG model?
ChatGPT is not inherently a RAG architecture. An application can connect an LLM service to an outside search system, but the setup determines whether retrieval occurs. The model might answer from its built-in capabilities, use connected sources, or use tools in a larger workflow. Check what information the specific application can access.
What are the best RAG models?
There is no single best RAG model for every task. A RAG system combines an LLM with retrieval and embedding components, and each choice affects cost, data handling, and answer quality. A small internal knowledge base may need different tools from a large document collection. Test candidate systems with your real questions and source material.
Is RAG becoming obsolete?
No. Long-context models help when you need to analyze a large supplied input that fits within one context window. Retrieval remains useful when information sits in a large or changing external collection. The choice depends on whether the task needs analysis of supplied material or selected facts from sources that can change.
What is the new alternative to RAG?
Agentic AI is one alternative for tasks that need planning and tool use across several steps, but it does not replace RAG in every case. A standard RAG system suits a bounded search-and-answer task. An agent can choose actions and adjust after seeing results. Some applications combine retrieval, rules, agents, and human review.
How do I build my own RAG model?
Start by choosing one use case and trusted source material. Index the content as chunks and embeddings, then retrieve relevant passages for a query and connect them to an LLM. Test the retrieved evidence as well as the answer. Keep the first project narrow so you can spot missing sources, weak matches, or access problems.
About The Author