AI Voice Generator for Natural Sounding Voices Online

A finished video, lesson or social post often needs one thing before it feels complete: clear spoken narration. CapCut’s online AI voice generator lets you create narration and keep working on the surrounding video project in one place.
You can use the workflow for videos, ads, social media posts, educational content, product demos, or an individual creative project. Keep the narration beside your visual editing, so you can shape the audio and image together as the work takes form.
The right sound depends on the audience, format, and words in your script. A style that suits a playful ad may not fit a lesson or audiobook, so a preview can help you make a more informed choice.
This page offers practical ways to choose a sound and prepare your script. Start with a short script and a clear idea of where its audio will be used.
Key Takeaways
- Try a short script before creating a full narration.
- Pick a voice style that suits your audience and format.
- Review language, pronunciation, and pacing in the preview.
- Match narration to your video, captions, and other audio.
- Check the tool’s license before publishing generated audio.
How Does an AI Voice Generator Turn Text Into Speech?
TTS turns written words into spoken audio, so the first useful test is a short passage you can listen to and revise. Text-to-speech (TTS) is software that turns written words into spoken audio.
Generation converts text into audio, but it does not make every line sound naturally spoken. CapCut’s workflow uses a text-to-speech action after you enter or paste text.
Prepare a script the model can read
Start with a few sentences that represent the full project. Include words, names, and sentence types that the final voice will need to handle.
A free AI voice generator text-to-speech tool can help you test a short passage before you commit to a full project. Treat that first result as a draft, not a finished performance.
- Prepare a short script with the words you plan to use.
- Choose a voice that fits the intended audience.
- Generate a preview and listen to the spoken audio.
- Revise the text, then export or place the audio in your project.
Generate a preview before building the final audio
Listen for words that sound wrong, pauses that break a phrase, or lines that feel too formal. A readable script can still sound stiff when spoken aloud.
Read the preview while following the script, then correct any word the voice pronounces incorrectly.
After revising, generate another preview to hear the changed wording in context. Keep the test passage short enough to review line by line.
Which Voice and Delivery Controls Should You Choose?
A calm explainer usually benefits from measured pacing, while a short social clip may need a livelier delivery. Start with the format, then judge each voice by how its sample sounds.
Pitch, volume, speed, accents, and emotional tone can change how the same words feel. CapCut offers pitch, volume, and speed controls, along with a voice changer.

A voice label is only a rough guide; a preview gives you a better sense of its tone. The browser Web Speech API also lets developers select available voices and adjust speech rate and pitch, as shown in the MDN Web Speech API guide.
| Delivery choice | Useful fit | Adjustment to try | What to listen for |
|---|---|---|---|
| Narrator | Lessons and explainers | Slow the speed slightly | Clear phrasing between key points |
| Conversational | Podcasts and product demos | Try a softer volume | Natural pauses, not a flat read |
| Energetic | Short ads and social clips | Raise the pace in small steps | Words remain easy to follow |
| Character-style | Animation and storytelling | Test a distinct pitch | Dialogue stays clear and consistent |
Voiser’s app listing describes pitch, speed, and emotional-tone adjustments. VEED offers previews with tones such as confident, conversational, and excited.
Test one adjustment at a time, and keep the original sample nearby for comparison. Keep one setting change at a time so you can hear which adjustment improves the line.
Can You Generate Speech in Other Languages?
For multilingual narration, check the exact language and model first, then test names and phrases that matter to your audience. Language support differs by tool and model, even within one service.
ElevenLabs has a free Hindi AI voice generator page, but access may differ by plan and model. Google AI Studio’s Gemini TTS supports more than 100 languages and native two-speaker dialogue.

Eleven v3 supports more than 70 languages and requests up to 5,000 characters. ElevenLabs Flash v2.5 allows requests up to 40,000 characters, a different limit for a different model.
Those caps matter when you plan to create a long voiceover or several audio tracks. A localization service can transcribe, translate, and create speech in another language; some businesses connect existing tools such as Whisper and ElevenLabs APIs for this work. See low-cost machine-learning startup ideas for an example of that service model.
Use a short test to hear how the model handles names, local terms, and region-specific wording. A script written for one audience may need different phrasing for another, even when the translation is accurate.
A short native-speaker review is a useful final check for pronunciation and phrasing.
How Do You Add a Voiceover to a Video?
If your visuals are already in place, create the narration in the same project and check how each line lands against the footage. A shared workspace can make it easier to compare spoken audio with the scene.
A free AI voice generator online can help when you want to create and edit in a browser. CapCut combines text-to-speech with video editing tools, including effects, music, sound effects, subtitles, transcription, and text overlay.
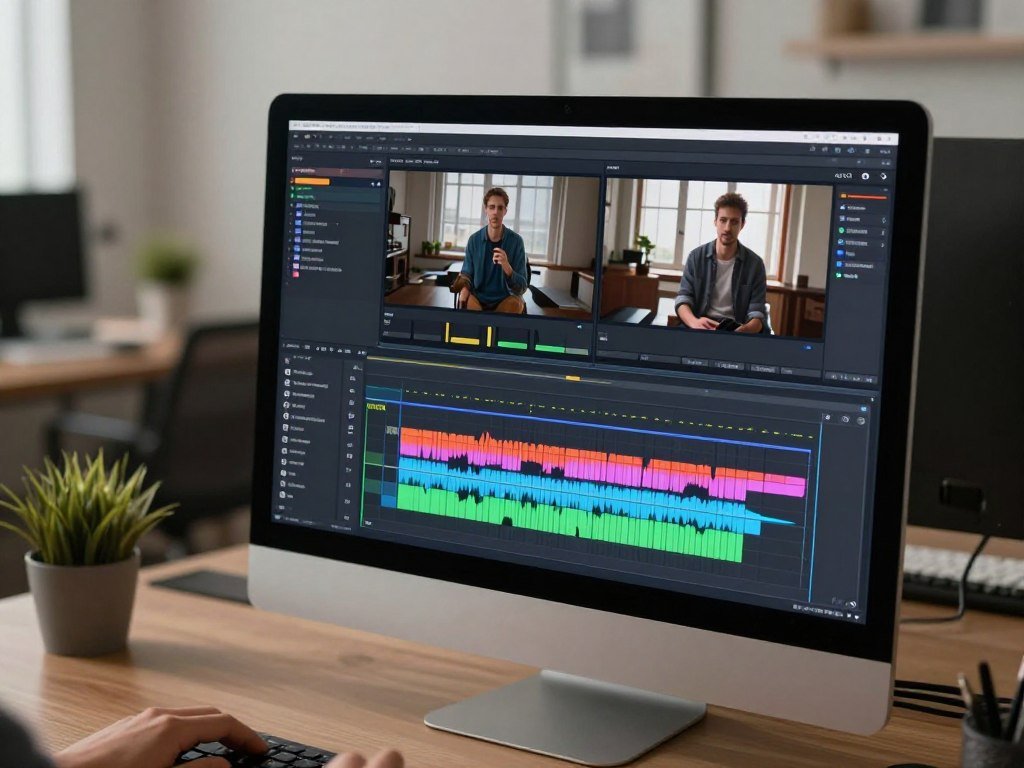
Adding narration does not finish the whole video. Music, captions, visual timing, and the balance between sounds still need review.
- Open an existing video project or start a new one.
- Enter or paste the narration script, then generate audio.
- Align the audio with the visuals in the timeline.
- Add captions or supporting sound, then export the video.
You can also begin with a blank canvas or uploaded footage. VEED’s workflow supports either start and lets you add music, captions, and brand graphics before export.
For a creator building ads or other business content, voiceover can be one part of a broader content service. Ideas for AI and SaaS tech startups in the US include AI-assisted marketing and content work.
Listen once with the visuals playing to catch gaps, overlaps, and lines that finish too early.
Which Free AI Voice Generator Fits Your Project?
For a creator editing a video in the browser, CapCut is the most direct starting point; choose another tool when its specific access rules better fit your task. Free access can mean different things, from a small test allowance to no sign-up.
Choose by the job you need done, then check the free tier’s limits. Microsoft Edge TTS is a candidate if you want no sign-up and broad stated access, while NoteGPT offers an account-free voice option.
Camb.ai can suit a short test, with a 500-character cap per generation. Murf offers more than 200 voices across 35-plus languages, but its free plan gives one-time access to 10 minutes of voice generation and blocks audio downloads.
Play.ht’s free plan provides 12,500 characters per month for non-commercial audio and requires attribution. Microsoft Edge TTS is described as free, effectively unlimited, and available without an account, with more than 300 neural voices across 70-plus languages.
| Tool | Useful starting case | Free access detail | Practical limitation |
|---|---|---|---|
| CapCut | Online narration with video editing | Free online access | No quota stated here |
| Murf | Testing voice styles | 10 minutes, one time | Free plan blocks downloads |
| Play.ht | Monthly text-to-speech use | 12,500 characters monthly | Non-commercial; attribution required |
| Microsoft Edge TTS | No-sign-up speech generation | Free, effectively unlimited | Check the workflow you need |
| Camb.ai | Very short sample generation | 500 characters per generation | Short request cap |
Edge TTS is described as having no character cap and allowing commercial use without an account. NoteGPT lists more than 100 voices in 40-plus languages without an account.
Speechify’s free plan has about 10 basic voices, limits playback speed to 1.5 times, and restricts free voices to personal use. Voiser’s app listing describes more than 550 voices in 75-plus languages and MP3 export.
When free access is not enough, Hume Octave plans start at $3 per month, while TTSMaker plans start at $13.99. WellSaid starts at $19, and Fish Audio starts at $15 per month; these are options to compare, not a universal pick.
Before committing to a free tier, check whether it permits downloads and the use you have in mind.
What Do Free and Paid Plans Actually Include?
A free tier is a good audition space, but its allowance, export access, and license determine whether it can support a finished project. Read the limits together: credits, characters, and minutes measure different kinds of use.
Free access or a downloadable file does not by itself grant commercial rights. ElevenLabs lists these plan prices and allowances:
| Plan | Monthly price | Allowance or standout inclusion |
|---|---|---|
| ElevenLabs Free | $0 | 10,000 credits, about 10 TTS minutes |
| ElevenLabs Starter | $6 | 30,000 credits; commercial license |
| ElevenLabs Creator | $22 | 121,000 credits; Professional Voice Cloning |
| ElevenLabs Pro | $99 | 600,000 credits; 44.1 kHz PCM through API |
| ElevenLabs Scale | $299 | 1.8 million credits; 3 seats |
Starter includes Instant Voice Cloning and Dubbing Studio. Pro includes 192 kbps output, while Scale includes three seats. The Business plan lists $990 per month, 6 million credits, and 10 seats.
Check free access, credits and commercial rights
ElevenLabs says paid credits can roll over for up to two months, capped at two monthly quotas plus the current month’s allowance. Free credits do not roll over.
Gemini TTS in AI Studio is free with rate limits, but free-tier audio is non-commercial. Commercial production requires paid Cloud billing.
Compare paid plans by usage, output and seats
Google Cloud TTS offers more than 380 voices in 75-plus languages and ongoing free use of standard voices up to 4 million characters monthly. Chirp 3 HD costs $30 per million characters; WaveNet and Neural2 cost $16 per million.
Amazon Polly’s 12-month free tier includes 5 million standard and 1 million neural characters per month. After that, standard voices cost $4 per million characters, neural voices cost $16, and its generative engine costs $30.
Azure F0 includes 500,000 characters monthly. Neural voices cost $16 per million characters, while Neural HD costs $22 per million.
Speechify Premium costs about $139 per year and includes more than 200 voices, 60-plus languages, faster playback, and offline downloads. Google Cloud TTS rates and other service charges use character counts, while subscriptions may use credits or minutes.
Prices and plan limits can change, so compare the current allowance with your expected output. Match the billed unit to your expected output, then confirm the license for the exact project you plan to publish.
How Can You Make Generated Speech Sound More Natural?
A voice often sounds more natural when the script is written to be spoken, not merely copied from a page. Small text changes can make a line easier for a voice model to read.
Listen to the rendered audio because punctuation and tags cannot guarantee the emphasis or pronunciation you want. Use these checks before creating a long narration:
- Shorten sentences that contain too many clauses.
- Add punctuation where a speaker would pause.
- Write out names or abbreviations that the model often misreads.
- Listen for steady pacing across adjacent lines.
A line with three ideas may be easier to follow as two short sentences. That small edit can also give the voice a more natural place to pause.
Emotional tags can signal a change in delivery. Fish Audio supports more than 60 inline tags, including directions such as whispering, excited, and laughing.
Gemini TTS supports native two-speaker dialogue, which can help when a script has clear turns between speakers. A tag or punctuation mark guides the model, but you still need to hear the result.
Re-render the sentence that sounds stiff before regenerating an entire chapter or long narration.
Can You Create Character Voices or Clone a Voice?
Character voices can make speakers easier to tell apart, while voice cloning is best reserved for a voice you have permission to use. Preset voices give you a ready-made sound; cloning uses a sample to reproduce a particular vocal identity.
Use your own voice or get permission before cloning someone else’s voice. An AI voice generator for characters can help distinguish roles in games, animation, storytelling, and dialogue.
Use voice cloning only with permission
ElevenLabs offers Instant Voice Cloning on Starter and Professional Voice Cloning on Creator. Fish Audio describes instant voice cloning from about 10 seconds of audio.
VEED offers voice cloning and says users can use their own voice in more than 25 languages. These tools can help keep a narrator’s vocal identity steady across different content.
Keep character dialogue distinct and consistent
For fiction, choose preset character voices when a distinct role matters more than copying a real speaker. Keep each role tied to one vocal identity throughout a scene.
Voices AI advertises more than 300 celebrity voices and speech-to-speech voice transformation. That catalog does not make an imitation an authorized endorsement, so do not present a real person as backing your ads or video.
Check applicable rights before public or commercial use, even when a tool offers a voice sample or preset. Keep a record of permission and the intended use whenever a real person’s voice is part of a project.
Is an Online or Local Browser Tool Better for Your Workflow?
Choose an online editor for an integrated video workflow, or a locally running browser model when keeping text on the device is a priority. The better fit depends on whether you need combined editing or local text processing.
SoundTools runs Kokoro locally in the browser and says it does not upload text to a server. Its model download is about 115 MB on first use, then the browser caches it.
SoundTools supports desktop browsers, not mobile browsers, because the model needs more memory. It lists more than 20 voices, including American and British English, with speed control from 0.5× to 2.0×.
The tool says there is no character limit and offers WAV and MP3 downloads without a watermark. Microsoft Edge TTS is described as requiring no sign-up or account and having no character cap.
A tool’s privacy statement is not a broader guarantee, and an audio download does not grant commercial permission.
Check whether your device can run the model before setting a production deadline. Check the tool’s device support, processing approach, and license before relying on it for a production deadline.
Conclusion
A short preview is the simplest way to find out whether a voice suits your script and audience. Test a few lines in a workflow that fits the project, then listen before building the full audio.
Check the tool’s usage rights before publishing or using generated audio commercially. A free test or an exported file does not settle that question.
Open CapCut, paste a few lines, generate a preview, and refine it before you build the full project.
FAQ
Can I use AI-generated voiceovers in monetized videos?
Yes, when the tool’s license and your plan allow commercial use. Free access alone does not grant that right, and a downloadable file does not prove permission. Check the terms for the specific voice and project, including ads or monetized videos. If the audio uses a cloned voice, you also need permission from the person whose voice it reproduces.
How many characters should I put in one TTS request?
Use the request cap for the model you selected. Eleven v3 allows up to 5,000 characters per request, while ElevenLabs Flash v2.5 allows up to 40,000 characters. Those limits do not mean every project should use the full amount. Shorter requests can be easier to review when you need to correct a pronunciation or revise a line.
Can a free AI voice generator export MP3 files?
Some can, but export rules vary by tool and plan. Murf’s free plan blocks audio downloads, while SoundTools says it offers MP3 and WAV downloads without a watermark. A download option does not grant commercial rights, so check both the export rules and the license. Keep a copy of the terms that apply to your planned use.
What is the difference between voice cloning and text-to-speech?
Text-to-speech reads written text in a selected voice, while voice cloning uses a sample to reproduce a particular vocal identity. TTS can create narration without copying a specific person. A cloned voice can sound like the speaker in the sample, so use your own voice or get permission before cloning someone else’s. Check rights for public or commercial use.
Can I make two speakers talk in one generated audio clip?
Yes, Google AI Studio’s Gemini TTS supports native two-speaker dialogue. That feature can suit a script with clear turns, such as an interview or short scene. Other tools may use separate voice clips instead, so check the selected model’s dialogue features. Listen to the full exchange to make sure each speaker’s turn is easy to follow.
Do browser-based voice tools work on phones?
Some work on phones, but SoundTools’ browser-based Kokoro tool supports desktop browsers and not mobile browsers. Its model needs more memory than the tool supports on mobile. A phone browser may still suit other online voice tools, depending on their features and device support. Test the workflow on the device you plan to use.
About The Author